

Reducing Hallucinated Transcripts in Whisper via Hallucination Space Projection
Paper • 2609.04561 • Published
id stringlengths 15 20 | audio audioduration (s) 0.58 12.2 | pattern stringclasses 4
values | unit stringclasses 17
values | n_repeats int32 3 12 | rate_hz float32 3 9 | tail_silence_s float32 0 8 | duration_s float32 0.58 12.2 | reference_text stringclasses 120
values | reference_collapsed stringclasses 120
values |
|---|---|---|---|---|---|---|---|---|---|
cv_tu_n03_r3_t0 | cv | tu | 3 | 3 | 0 | 1.25 | tu tu tu | tututu | |
cv_tu_n03_r3_t2 | cv | tu | 3 | 3 | 2 | 3.25 | tu tu tu | tututu | |
cv_tu_n03_r3_t8 | cv | tu | 3 | 3 | 8 | 9.25 | tu tu tu | tututu | |
cv_tu_n03_r5_t0 | cv | tu | 3 | 5 | 0 | 0.85 | tu tu tu | tututu | |
cv_tu_n03_r5_t2 | cv | tu | 3 | 5 | 2 | 2.85 | tu tu tu | tututu | |
cv_tu_n03_r5_t8 | cv | tu | 3 | 5 | 8 | 8.85 | tu tu tu | tututu | |
cv_tu_n03_r7_t0 | cv | tu | 3 | 7 | 0 | 0.678 | tu tu tu | tututu | |
cv_tu_n03_r7_t2 | cv | tu | 3 | 7 | 2 | 2.678 | tu tu tu | tututu | |
cv_tu_n03_r7_t8 | cv | tu | 3 | 7 | 8 | 8.678 | tu tu tu | tututu | |
cv_tu_n03_r9_t0 | cv | tu | 3 | 9 | 0 | 0.583 | tu tu tu | tututu | |
cv_tu_n03_r9_t2 | cv | tu | 3 | 9 | 2 | 2.583 | tu tu tu | tututu | |
cv_tu_n03_r9_t8 | cv | tu | 3 | 9 | 8 | 8.583 | tu tu tu | tututu | |
cv_tu_n04_r3_t0 | cv | tu | 4 | 3 | 0 | 1.583 | tu tu tu tu | tutututu | |
cv_tu_n04_r3_t2 | cv | tu | 4 | 3 | 2 | 3.583 | tu tu tu tu | tutututu | |
cv_tu_n04_r3_t8 | cv | tu | 4 | 3 | 8 | 9.583 | tu tu tu tu | tutututu | |
cv_tu_n04_r5_t0 | cv | tu | 4 | 5 | 0 | 1.05 | tu tu tu tu | tutututu | |
cv_tu_n04_r5_t2 | cv | tu | 4 | 5 | 2 | 3.05 | tu tu tu tu | tutututu | |
cv_tu_n04_r5_t8 | cv | tu | 4 | 5 | 8 | 9.05 | tu tu tu tu | tutututu | |
cv_tu_n04_r7_t0 | cv | tu | 4 | 7 | 0 | 0.821 | tu tu tu tu | tutututu | |
cv_tu_n04_r7_t2 | cv | tu | 4 | 7 | 2 | 2.821 | tu tu tu tu | tutututu | |
cv_tu_n04_r7_t8 | cv | tu | 4 | 7 | 8 | 8.821 | tu tu tu tu | tutututu | |
cv_tu_n04_r9_t0 | cv | tu | 4 | 9 | 0 | 0.694 | tu tu tu tu | tutututu | |
cv_tu_n04_r9_t2 | cv | tu | 4 | 9 | 2 | 2.694 | tu tu tu tu | tutututu | |
cv_tu_n04_r9_t8 | cv | tu | 4 | 9 | 8 | 8.694 | tu tu tu tu | tutututu | |
cv_tu_n05_r3_t0 | cv | tu | 5 | 3 | 0 | 1.916 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r3_t2 | cv | tu | 5 | 3 | 2 | 3.916 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r3_t8 | cv | tu | 5 | 3 | 8 | 9.916 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r5_t0 | cv | tu | 5 | 5 | 0 | 1.25 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r5_t2 | cv | tu | 5 | 5 | 2 | 3.25 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r5_t8 | cv | tu | 5 | 5 | 8 | 9.25 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r7_t0 | cv | tu | 5 | 7 | 0 | 0.964 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r7_t2 | cv | tu | 5 | 7 | 2 | 2.964 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r7_t8 | cv | tu | 5 | 7 | 8 | 8.964 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r9_t0 | cv | tu | 5 | 9 | 0 | 0.805 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r9_t2 | cv | tu | 5 | 9 | 2 | 2.805 | tu tu tu tu tu | tututututu | |
cv_tu_n05_r9_t8 | cv | tu | 5 | 9 | 8 | 8.805 | tu tu tu tu tu | tututututu | |
cv_tu_n06_r3_t0 | cv | tu | 6 | 3 | 0 | 2.249 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r3_t2 | cv | tu | 6 | 3 | 2 | 4.25 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r3_t8 | cv | tu | 6 | 3 | 8 | 10.249 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r5_t0 | cv | tu | 6 | 5 | 0 | 1.45 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r5_t2 | cv | tu | 6 | 5 | 2 | 3.45 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r5_t8 | cv | tu | 6 | 5 | 8 | 9.45 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r7_t0 | cv | tu | 6 | 7 | 0 | 1.107 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r7_t2 | cv | tu | 6 | 7 | 2 | 3.107 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r7_t8 | cv | tu | 6 | 7 | 8 | 9.107 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r9_t0 | cv | tu | 6 | 9 | 0 | 0.916 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r9_t2 | cv | tu | 6 | 9 | 2 | 2.916 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n06_r9_t8 | cv | tu | 6 | 9 | 8 | 8.916 | tu tu tu tu tu tu | tutututututu | |
cv_tu_n08_r3_t0 | cv | tu | 8 | 3 | 0 | 2.916 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r3_t2 | cv | tu | 8 | 3 | 2 | 4.916 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r3_t8 | cv | tu | 8 | 3 | 8 | 10.916 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r5_t0 | cv | tu | 8 | 5 | 0 | 1.85 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r5_t2 | cv | tu | 8 | 5 | 2 | 3.85 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r5_t8 | cv | tu | 8 | 5 | 8 | 9.85 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r7_t0 | cv | tu | 8 | 7 | 0 | 1.393 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r7_t2 | cv | tu | 8 | 7 | 2 | 3.393 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r7_t8 | cv | tu | 8 | 7 | 8 | 9.393 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r9_t0 | cv | tu | 8 | 9 | 0 | 1.139 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r9_t2 | cv | tu | 8 | 9 | 2 | 3.139 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n08_r9_t8 | cv | tu | 8 | 9 | 8 | 9.139 | tu tu tu tu tu tu tu tu | tutututututututu | |
cv_tu_n12_r3_t0 | cv | tu | 12 | 3 | 0 | 4.249 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r3_t2 | cv | tu | 12 | 3 | 2 | 6.249 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r3_t8 | cv | tu | 12 | 3 | 8 | 12.249 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r5_t0 | cv | tu | 12 | 5 | 0 | 2.65 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r5_t2 | cv | tu | 12 | 5 | 2 | 4.65 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r5_t8 | cv | tu | 12 | 5 | 8 | 10.65 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r7_t0 | cv | tu | 12 | 7 | 0 | 1.964 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r7_t2 | cv | tu | 12 | 7 | 2 | 3.964 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r7_t8 | cv | tu | 12 | 7 | 8 | 9.964 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r9_t0 | cv | tu | 12 | 9 | 0 | 1.583 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r9_t2 | cv | tu | 12 | 9 | 2 | 3.583 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_tu_n12_r9_t8 | cv | tu | 12 | 9 | 8 | 9.583 | tu tu tu tu tu tu tu tu tu tu tu tu | tutututututututututututu | |
cv_ta_n03_r3_t0 | cv | ta | 3 | 3 | 0 | 1.25 | ta ta ta | tatata | |
cv_ta_n03_r3_t2 | cv | ta | 3 | 3 | 2 | 3.25 | ta ta ta | tatata | |
cv_ta_n03_r3_t8 | cv | ta | 3 | 3 | 8 | 9.25 | ta ta ta | tatata | |
cv_ta_n03_r5_t0 | cv | ta | 3 | 5 | 0 | 0.85 | ta ta ta | tatata | |
cv_ta_n03_r5_t2 | cv | ta | 3 | 5 | 2 | 2.85 | ta ta ta | tatata | |
cv_ta_n03_r5_t8 | cv | ta | 3 | 5 | 8 | 8.85 | ta ta ta | tatata | |
cv_ta_n03_r7_t0 | cv | ta | 3 | 7 | 0 | 0.678 | ta ta ta | tatata | |
cv_ta_n03_r7_t2 | cv | ta | 3 | 7 | 2 | 2.678 | ta ta ta | tatata | |
cv_ta_n03_r7_t8 | cv | ta | 3 | 7 | 8 | 8.678 | ta ta ta | tatata | |
cv_ta_n03_r9_t0 | cv | ta | 3 | 9 | 0 | 0.583 | ta ta ta | tatata | |
cv_ta_n03_r9_t2 | cv | ta | 3 | 9 | 2 | 2.583 | ta ta ta | tatata | |
cv_ta_n03_r9_t8 | cv | ta | 3 | 9 | 8 | 8.583 | ta ta ta | tatata | |
cv_ta_n04_r3_t0 | cv | ta | 4 | 3 | 0 | 1.583 | ta ta ta ta | tatatata | |
cv_ta_n04_r3_t2 | cv | ta | 4 | 3 | 2 | 3.583 | ta ta ta ta | tatatata | |
cv_ta_n04_r3_t8 | cv | ta | 4 | 3 | 8 | 9.583 | ta ta ta ta | tatatata | |
cv_ta_n04_r5_t0 | cv | ta | 4 | 5 | 0 | 1.05 | ta ta ta ta | tatatata | |
cv_ta_n04_r5_t2 | cv | ta | 4 | 5 | 2 | 3.05 | ta ta ta ta | tatatata | |
cv_ta_n04_r5_t8 | cv | ta | 4 | 5 | 8 | 9.05 | ta ta ta ta | tatatata | |
cv_ta_n04_r7_t0 | cv | ta | 4 | 7 | 0 | 0.821 | ta ta ta ta | tatatata | |
cv_ta_n04_r7_t2 | cv | ta | 4 | 7 | 2 | 2.821 | ta ta ta ta | tatatata | |
cv_ta_n04_r7_t8 | cv | ta | 4 | 7 | 8 | 8.821 | ta ta ta ta | tatatata | |
cv_ta_n04_r9_t0 | cv | ta | 4 | 9 | 0 | 0.694 | ta ta ta ta | tatatata | |
cv_ta_n04_r9_t2 | cv | ta | 4 | 9 | 2 | 2.694 | ta ta ta ta | tatatata | |
cv_ta_n04_r9_t8 | cv | ta | 4 | 9 | 8 | 8.694 | ta ta ta ta | tatatata | |
cv_ta_n05_r3_t0 | cv | ta | 5 | 3 | 0 | 1.916 | ta ta ta ta ta | tatatatata | |
cv_ta_n05_r3_t2 | cv | ta | 5 | 3 | 2 | 3.916 | ta ta ta ta ta | tatatatata | |
cv_ta_n05_r3_t8 | cv | ta | 5 | 3 | 8 | 9.916 | ta ta ta ta ta | tatatatata | |
cv_ta_n05_r5_t0 | cv | ta | 5 | 5 | 0 | 1.25 | ta ta ta ta ta | tatatatata |
This is a benchmark. Every evaluation config is
test— do not fine-tune on it.lexicon_synthis the exception: synthetic training material with its owntrain/testsplit, and not one of the eight benchmark arms.To build training data, exclude the items in
benchmark/exclusions.json(546 FMA tracks, 1,168 FSD50K ids, 2,620 LibriSpeech utterances, the Malay stems). The benchmark draws FSD50K eval and FMA shards 0–1, so training can use FSD50K dev and FMA shards 2–12 with no overlap.
Audio probes and phrase lexicons for two Whisper failure modes:
Terima kasih. over silence)Code and build scripts: github.com/Scicom-AI-Enterprise-Organization/Whisper-Hallucination
Every common Whisper hallucination is also a phrase people say. terima kasih is the most
common Malay hallucination and the most common thing a call-centre agent says. A text
blocklist deletes both.
| audio | model says | correct action |
|---|---|---|
| silence | Terima kasih. |
drop |
| music / noise | Terima kasih. |
drop |
| speech in noise | part real, part invented | the hard case |
| someone says it | Terima kasih. |
keep |
Silence is not the only trigger. Calm-Whisper measured large-v3 producing text on 99.97% of UrbanSound8K clips, none of which contain speech. Energy is not evidence for words.
Five checkpoints, 11,852 clips each, greedy decoding, no forced language, no temperature fallback. 2026-09-16/17 on 2× H20.
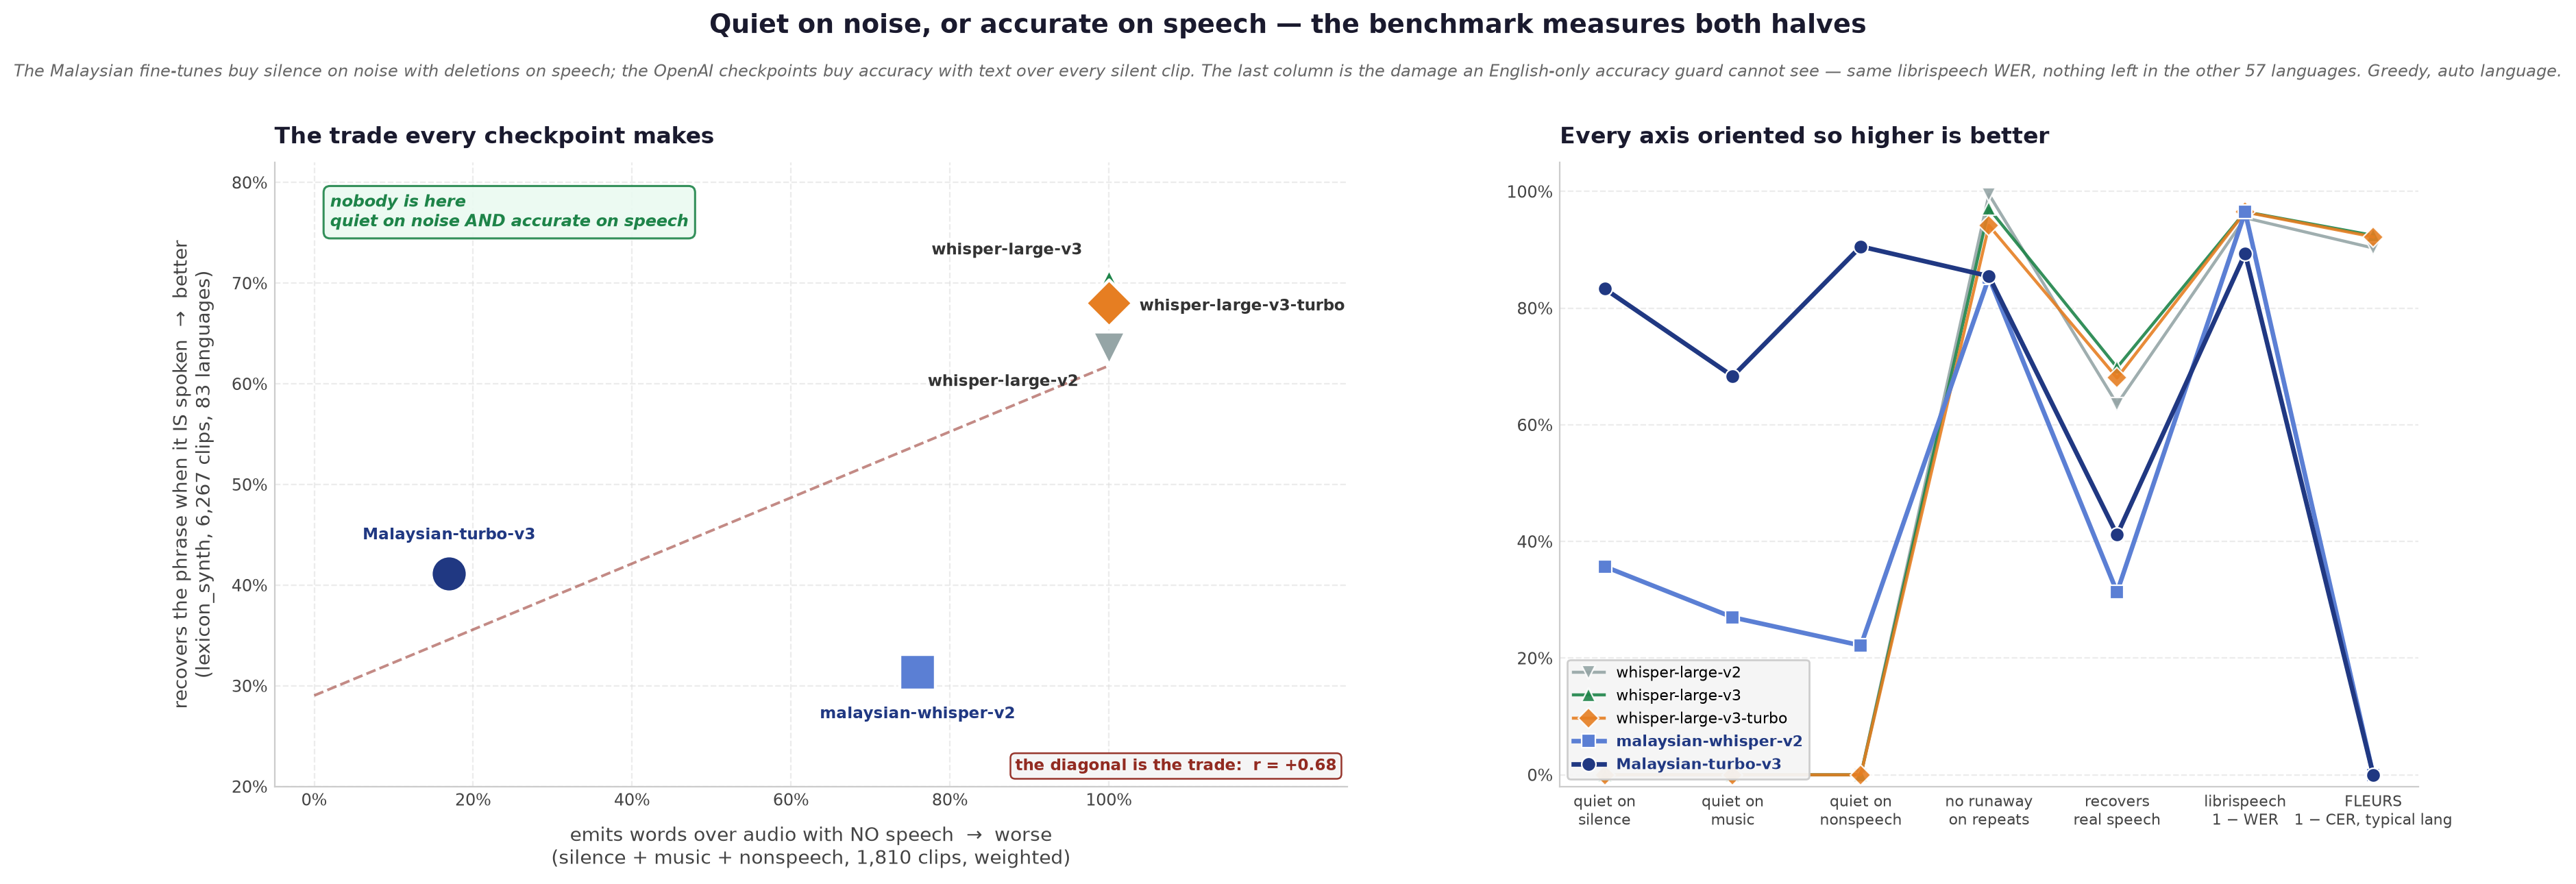
No checkpoint is both quiet on noise and accurate on speech. They sit on a line (r = +0.68).
| large-v2 | large-v3 | turbo | malaysian-v2 | M-turbo-v3 | |
|---|---|---|---|---|---|
hallucinates on nonspeech |
98.8% | 89.9% | 80.7% | 76.0% | 9.3% |
emits anything on silence |
100% | 100% | 100% | 64.3% | 16.7% |
runaway on reduplication |
0.5% | 2.9% | 5.8% | 14.7% | 14.5% |
emits nothing on reduplication |
0.0% | 0.1% | 5.2% | 16.9% | 58.0% |
| recovers a phrase that IS spoken | 63.6% | 69.8% | 68.0% | 31.3% | 41.1% |
librispeech WER |
4.5% | 3.5% | 3.5% | 3.5% | 10.6% |
Ranked on hallucination alone, Malaysian-turbo-v3 wins by a distance. Ranked on recovering
real speech it comes last. Measuring both on the same clips is the point.
Full tables: README.
Raw numbers: bench/scores.json. Harness: bench/.
| config | rows | hours | content | ground truth |
|---|---|---|---|---|
reduplication |
1,440 | 1.9 | repeated units — syllables, vowels, laughter, clicks | exactly n_repeats repeats |
silence |
42 | 0.4 | 6 noise floors × 7 durations | empty string |
music |
600 | 4.5 | real Free Music Archive excerpts | empty string |
nonspeech |
1,168 | 2.8 | FSD50K, label-verified voice-free | empty string |
speech_in_noise |
1,200 | 3.1 | genuine speech + background, 5 SNRs | the real transcript |
genuine |
4,694 | 12.4 | real Malaysian speech | human transcript |
genuine_isolated |
88 | 0.05 | one phrase spoken alone | the phrase |
librispeech_test_clean |
2,620 | 5.4 | English WER guard | human transcript |
lexicon_synth |
29,112 | 15.8 | synthetic positives, 83 languages | the phrase |
wild |
8,296 | 15.0 | real audio that triggered hallucination or looping | see below |
ships train (3,628) and test (4,668) |
||||
lexicon |
40,891 | — | known hallucination phrases, 100 languages | — |
ban_candidates |
40,891 | — | each phrase classified safe/unsafe to blocklist | — |
targets |
463 | — | phrases both hallucinated and genuinely said | — |
malaysian_sources |
24 | — | survey of public Malaysian speech datasets | — |
Audio is 16 kHz mono FLAC, peak-normalised to −3 dBFS.
datasets >= 5.0 demands torchcodec to touch an audio column. Skip it:
import io, soundfile as sf
from datasets import load_dataset, Audio

ds = load_dataset("Scicom-intl/Whisper-Hallucination", "reduplication", split="test")
ds = ds.cast_column("audio", Audio(decode=False))      # hand back raw bytes
x, sr = sf.read(io.BytesIO(ds[0]["audio"]["bytes"]), dtype="float32")
streaming=True works the same way. Lookup tables (lexicon, ban_candidates, targets,
malaysian_sources) load with split="train".
lexicon_synth — synthetic positives
Not a benchmark arm. Training material: 29,112 clips of lexicon phrases being spoken.
| train | test | |
|---|---|---|
| clips | 22,845 | 6,267 |
| hours | 12.49 | 3.32 |
| distinct phrases | 11,018 | 3,054 |
| languages | 75 | 83 |
| non-English share | 92% | 91% |
| named voices | 45 | 45 |
Split by phrase, not by clip. Each phrase is rendered in several voices. Splitting clips
would put terima kasih in both halves. Assignment is a hash of (phrase, language) with a
fixed salt.
306 phrases are forced into test because they appear in targets and drive the
genuine_isolated arm. The build verifies zero phrase overlap and zero benchmark phrases in
train, and refuses to write a release otherwise.
Phrases come from three places; meta.phrase_provenance says which:
| provenance | what it is |
|---|---|
observed |
phrases Whisper was seen to hallucinate (upstream lexicons) |
mined |
what these five checkpoints emitted on our non-speech arms |
translated |
English hallucination phrases rendered into 80 languages by NLLB-200 |
translated rows are positives, not evidence. A Tamil thank you is something people
say, not something Whisper was observed to invent in Tamil. Do not feed them back into
ban_candidates.
Audio comes from Scicom-intl/Multilingual-Expressive-TTS-1.7B (speaker-name conditioned)
and k2-fsa/OmniVoice, routed per language by measured CER. meta is a JSON string per clip
with model, codec, conditioning mode, speaker, sample rates, decoding parameters and seed.
voice is a label, not a measurement.
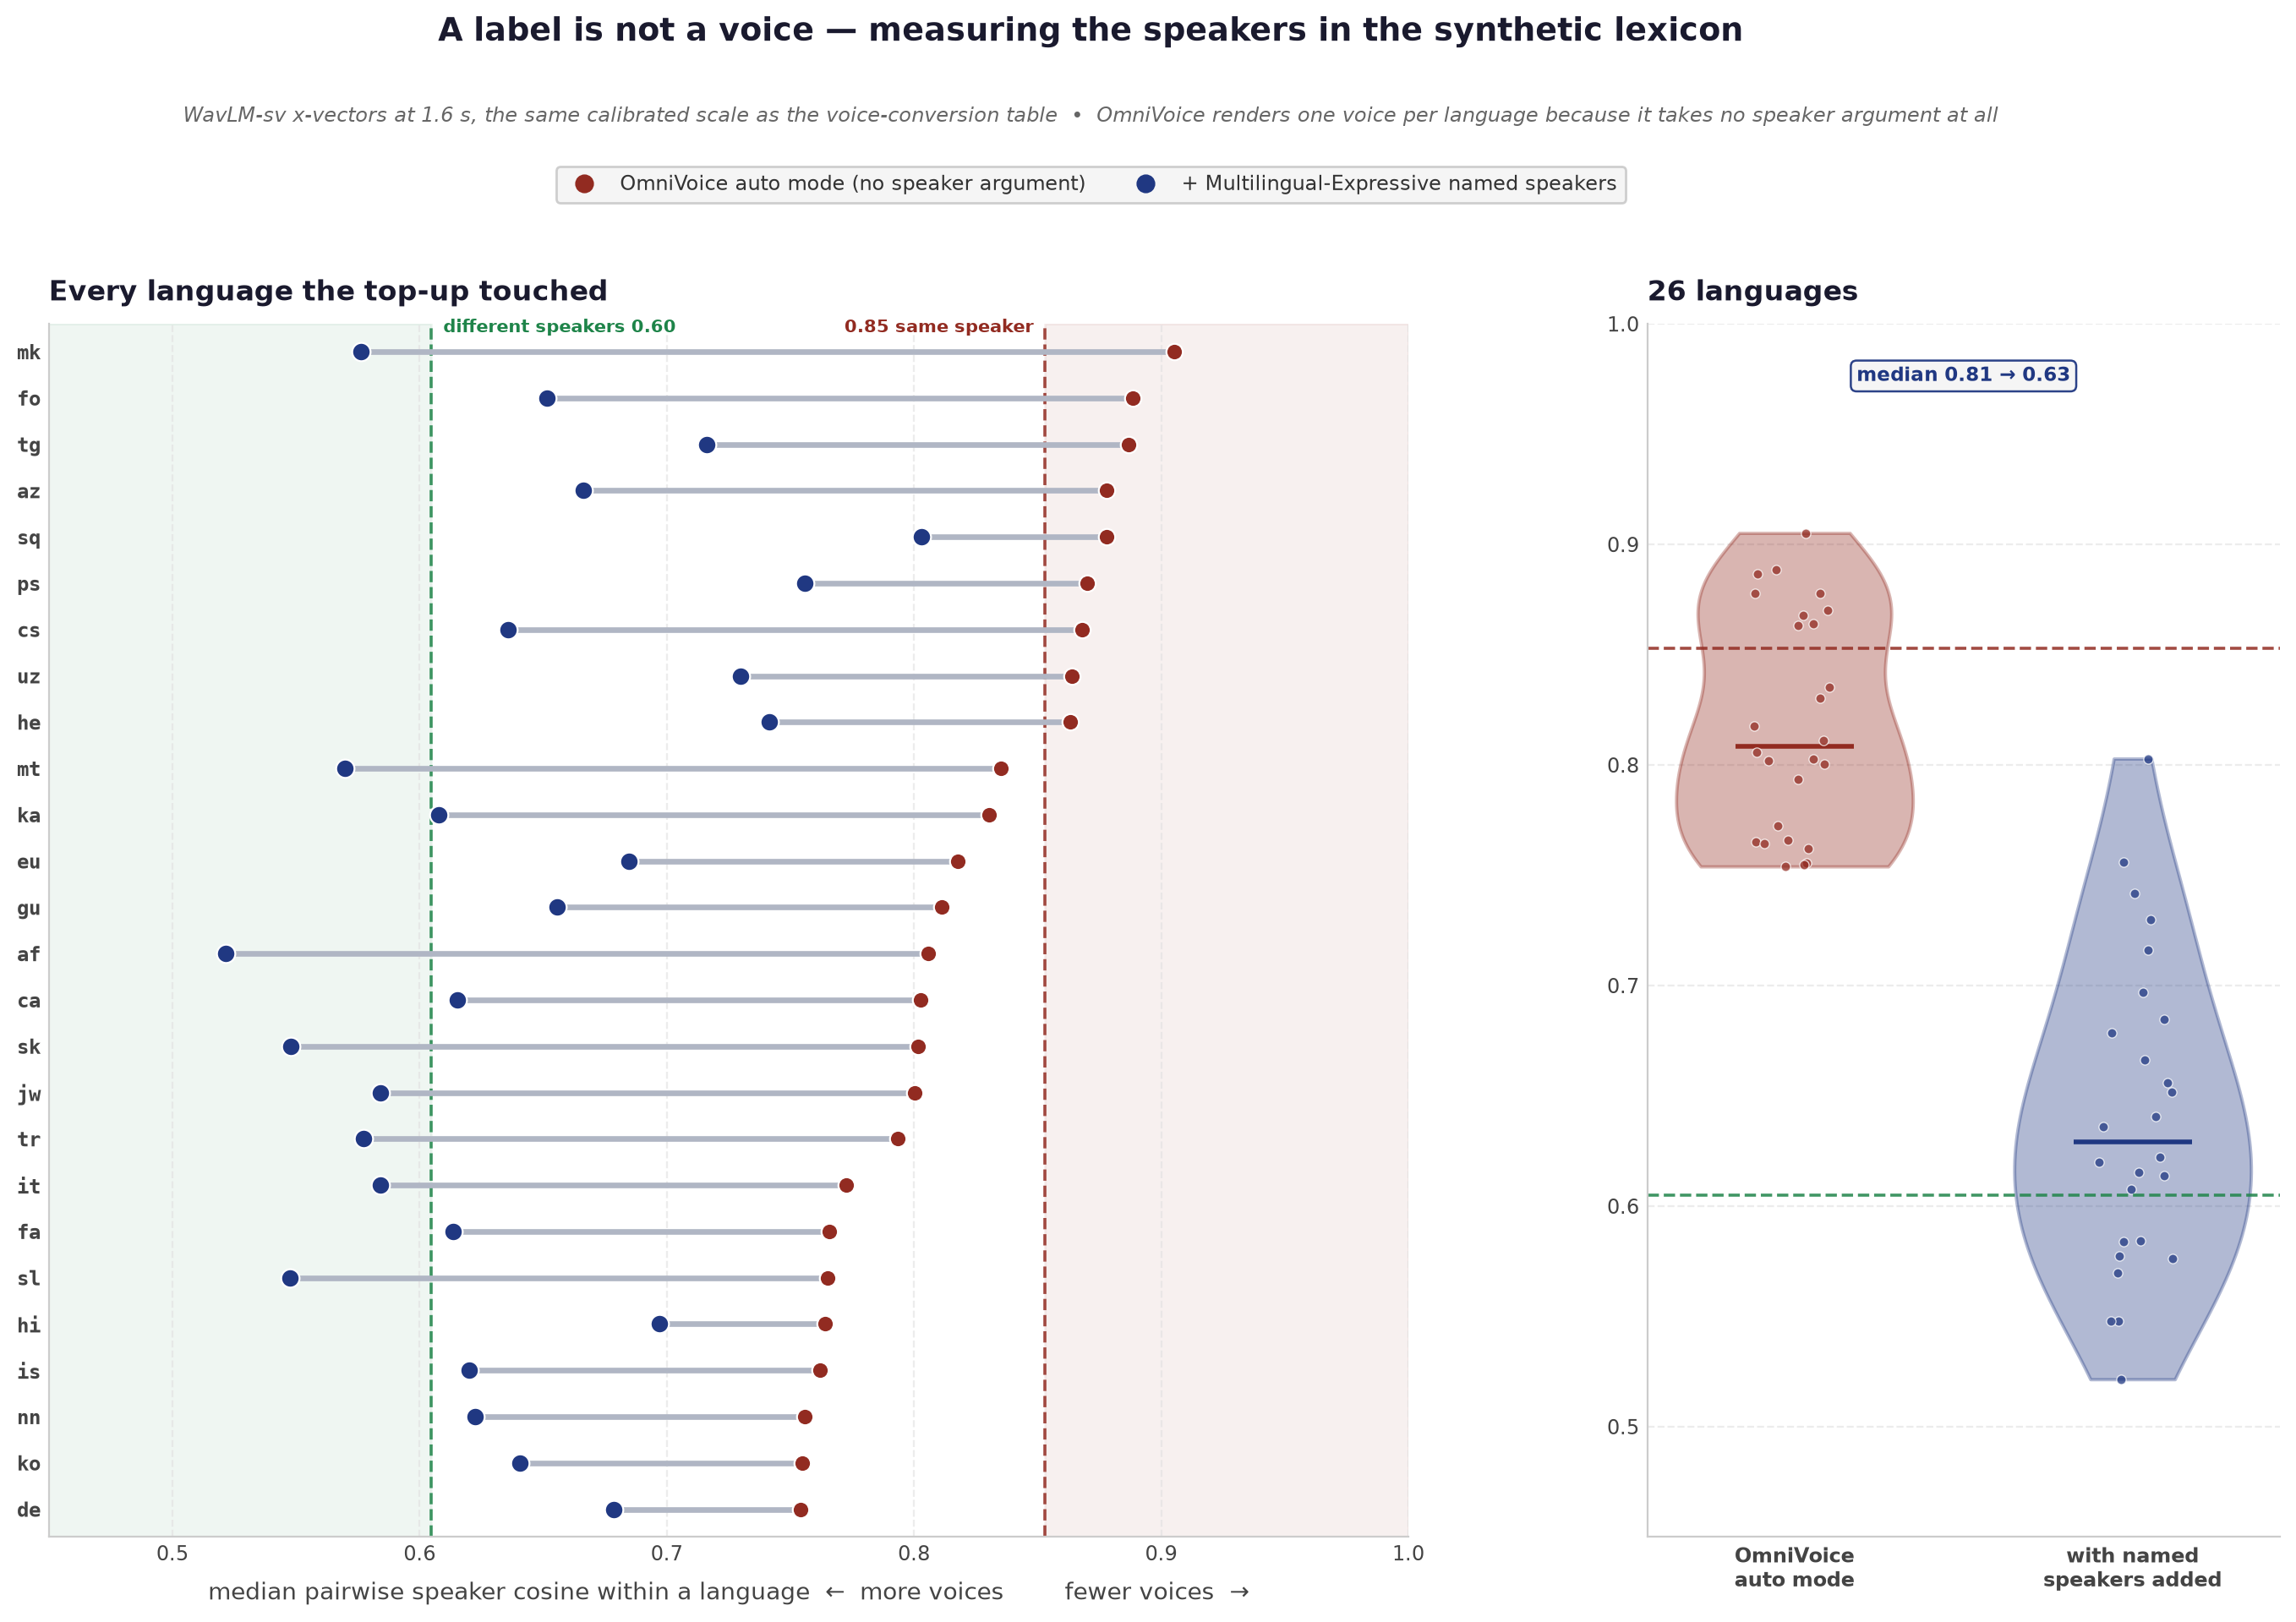
OmniVoice takes no speaker argument, so its clips carry voice="". Measured with WavLM-sv
x-vectors on a calibrated scale (0.61 = different speakers, 0.85 = same speaker, both at
1.6 s), 33 of its 74 languages sat at 0.75 or worse — one voice per language. The
Multilingual-Expressive clips measured 0.63, with same-name pairs at 0.83 and different-name
pairs at 0.60.
So 26 languages were topped up, not replaced: three extra named voices per phrase, the
auto-mode clip kept. 12,190 of 15,675 new clips passed the filter (77.8%), and the median
collapsed language moved 0.81 → 0.63. meta.conditioning distinguishes speaker_name from
language_id.
Seven languages were skipped (am ml my sd si te sr): the ASR judge cannot read them well
enough to validate any voice. That is a judge-coverage limit, not a quality claim.
Every clip passed an ASR round-trip: Whisper must recover the phrase, and the clip must be about as long as the phrase should take. The gate is per language, anchored to the judge's own floor — Whisper's CER on real FLEURS speech in 44 languages. A language where the judge itself scores 0.88 (Burmese) or 1.23 (Amharic) cannot be held to a 0.25 gate. Nine such languages are excluded rather than scored.
wild — real audio that actually failed
Every other audio config is a built stimulus. This one is not constructed at all: 8,296 clips, 15 hours, of real recordings where an ASR model hallucinated or looped.
| collection | clips | how it was labelled |
|---|---|---|
halas |
3,607 | human span annotations for 9 ASR systems, on Earnings-22 calls |
audioset |
4,376 | mined: Silero VAD found no speech, yet the model emitted words |
ami |
235 | mined, same rule |
earnings22 |
31 | mined, same rule |
gigaspeech_xs |
33 | mined, same rule |
peoples_dirty |
9 | mined: token run ≥ 6 |
voxpopuli |
4 | mined: token run ≥ 6 |
peoples_speech |
1 | mined: token run ≥ 6 |
Ships train (3,628) and test (4,668), split by SOURCE RECORDING. Several AudioSet clips
come from one YouTube video and a dozen HALAS segments from one earnings call, so a clip-level
split would put near neighbours on both sides and inflate the test score. Two things are held
out by rule rather than by hash:
test — the only human-labelled part of the arm, and the flagship wild
evaluation. Training on it would buy a little data and cost the benchmark.loop clip is test — there is no reference transcript, so no target to train
toward.What is trainable is the mined blank_speech material: real audio a VAD confirms contains no
speech, whose correct target is the empty string. Same lesson as the synthetic blank arms, on
audio that actually occurs.
reasons says which rule caught the clip. models_flagged and n_models_flagged carry the
HALAS human verdicts. reference_text is the human-corrected transcript where one exists.
No human labelling was needed for the mined clips, because two failure signatures are self-evident: a token run ≥ 6 (a correct transcript essentially never repeats one token six times), and words emitted where a VAD finds no speech. Clips are never called hallucinations merely because a transcript disagrees with a reference — that finds ordinary ASR errors.
Mining yield says where these failures live:
| corpus | heard | kept | rate |
|---|---|---|---|
| AudioSet — YouTube, heavy background noise | 8,000 | 4,376 | 54.70% |
| AMI — spontaneous meetings, far-field | 8,000 | 235 | 2.94% |
| GigaSpeech — podcasts + YouTube, speech-aligned | 8,000 | 33 | 0.41% |
| Earnings-22 — conference calls | 8,000 | 31 | 0.39% |
People's Speech dirty — noisy transcripts, clean audio |
8,000 | 9 | 0.11% |
| VoxPopuli — parliament | 8,000 | 4 | 0.05% |
People's Speech clean — curated read speech |
8,000 | 1 | 0.01% |
Yield tracks recording quality across five thousandfold. GigaSpeech is podcasts and YouTube — the right material — and still yields 0.41%, because its segments are cut to speech. The failures live in what segmentation throws away: music beds, crosstalk, the gaps between turns.
Baselines on this arm are in the project repo
README.
The short version: on 4,421 voice-free clips every OpenAI checkpoint emits words on 100% of
them while Malaysian-turbo-v3 emits on 8.5%, and 54–72% of those outputs are known lexicon
phrases (so ×909, ¶¶ ×664, Thank you. ×70). On HALAS speech clips the same rate is ~18%
whether humans marked the clip hallucinated or clean — a 3.8-point gap, which is why a text
blocklist cannot do this job. Error against the human reference separates the same clips by 22
points.
Not included: the 187 Koenecke aphasia clips. That is clinical speech from a membership-gated
corpus, so consent rather than licence keeps it out; scripts/fetch_audio.py aphasia gets it
for local measurement.
reduplication
A recording of tu repeated four times decoded as tu repeated until the token limit.
Inside a repeated-token region the decoder has no signal for how many repeats remain.
| field | values |
|---|---|
pattern |
cv (720), vowel (360), laugh (216), click (144) |
unit |
tu ta ka pa da la na bi ko me / a i u e o / ha he hi / tick beep |
n_repeats |
3, 4, 5, 6, 8, 12 |
rate_hz |
3, 5, 7, 9 |
tail_silence_s |
0, 2, 8 |
click contains no speech, which separates repetition from speech as the trigger. Nothing
here is tied to a language.
Score with n_hyp / n_repeats: 1.0 correct, >1 runaway, <1 a mitigation that deleted
genuine repetition.
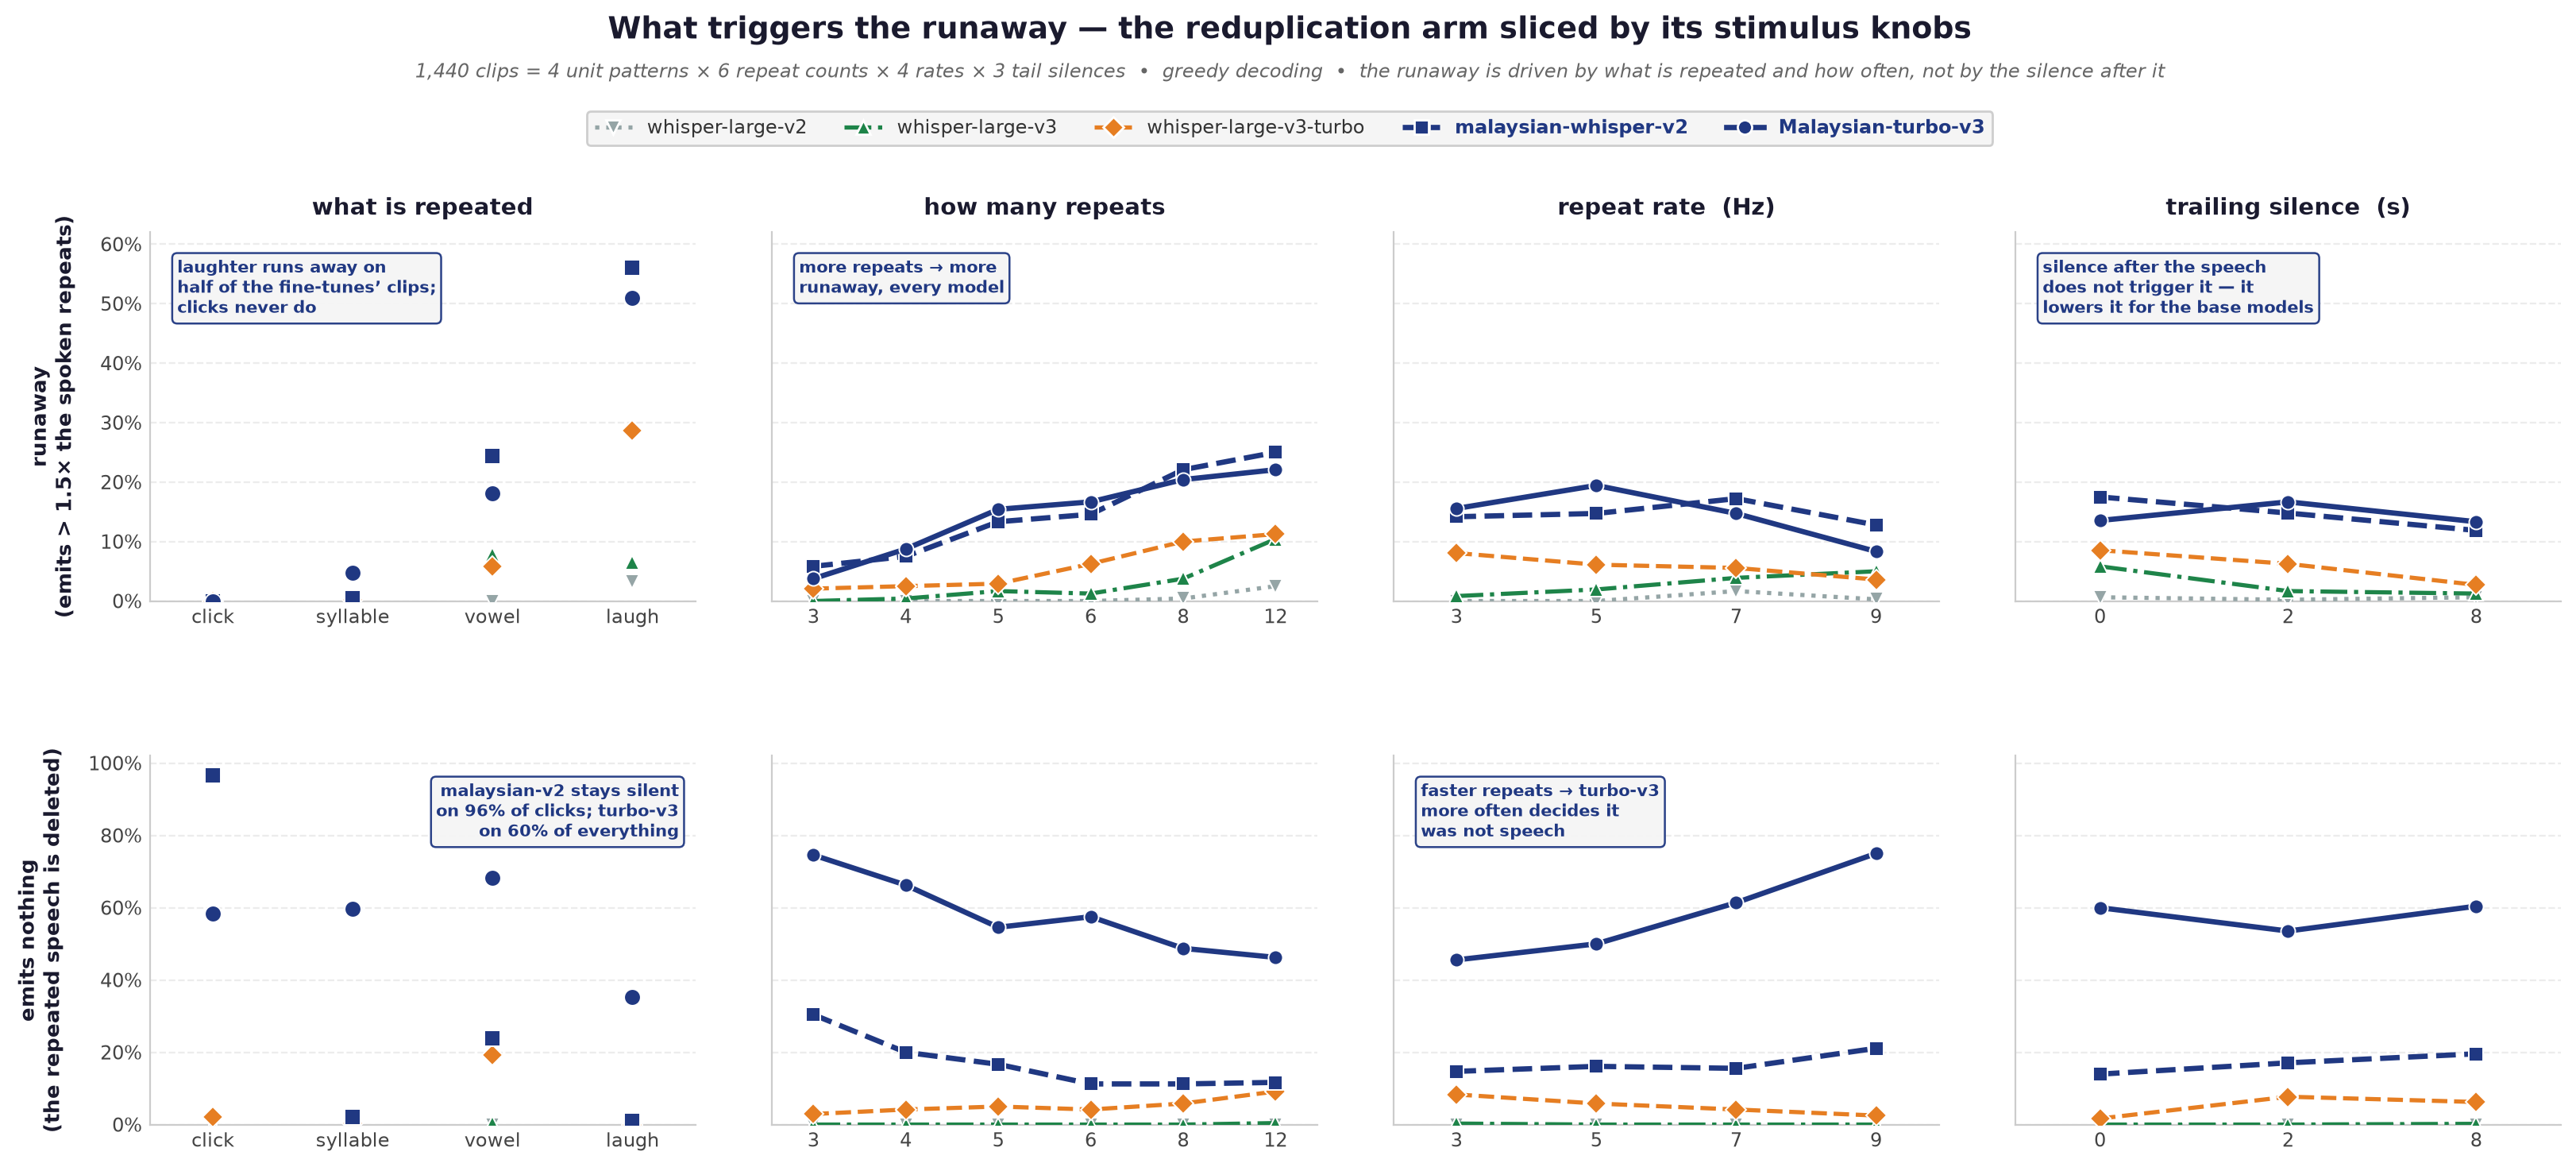
Laughter is the trigger (fine-tunes run away on 51–56% of laugh clips, 0% of clicks). More repeats means more runaway. Trailing silence does not cause it.
silence
Reference is the empty string, so any output is a hallucination. floor covers
digital_zero, dither, hiss_-60db, hiss_-45db, hum_50hz, roomtone. Durations
straddle the 30 s window: 1, 5, 10, 29, 31, 60, 120 s.
music
Real produced music, not sound effects: Free Music Archive tracks (commercial subset, CC BY 4.0), excerpted at 10 / 30 / 45 s so intros are skipped. This is what plays under a call — hold music, a backing bed.
FMA ships no vocal tag, so some tracks contain singing and vocals records unknown. If you
need provably zero words, use nonspeech.
nonspeech
FSD50K clips with no voice label of any kind — 583 music, 585 environmental and mechanical
noise. Anything labelled Speech, Singing, Human_voice, Chatter, Laughter or 20-odd
relatives was excluded, so the empty reference is verified by annotation.
speech_in_noise
Genuine speech with a background bed, where transcription degrades into fabrication as
evidence weakens. 240 clips from genuine mixed with voice-free FSD50K at SNR +20, +10, +5,
0, −5 dB. Reference is the real transcript. 295 of 1,200 carry a target phrase.
Without these, "hallucination rate fell" is unfalsifiable — a decoder that outputs nothing scores perfectly on the negative arms.
genuine
| source | clips | licence | register |
|---|---|---|---|
SaLTUNIMAS/sarawak-malay-asr |
1,164 | CC BY 4.0 | Sarawak Malay interviews |
emhaihsan/Synth-Manglish |
2,457 | CC BY 4.0 | Manglish code-switching (synthetic TTS) |
google/fleurs ms_my |
1,073 | CC BY 4.0 | human-read Wikipedia prose |
59 clips carry a high-risk phrase (has_target_phrase = true): sama-sama ×41,
terima kasih ×16, selamat tinggal ×2, terima kasih banyak banyak ×1. The rest are the
regression guard.
librispeech_test_clean
LibriSpeech test-clean (CC BY 4.0), the split the mitigation literature reports its cost on.
Hallucination-space projection on large-v3 (arXiv:2609.04561):
| variant | ESC-50 HR | LibriSpeech WER clean / other |
|---|---|---|
| baseline | 44.25% | 4.06% / 5.87% |
| gated projection | 8.38% | 6.17% / 6.57% |
| always-on projection | 1.50% | 12.95% / 13.13% |
Suppressing hallucination triples clean WER. That exchange rate is why the positive arms exist.
genuine_isolated
Native speakers from Lingua Libre saying one phrase and nothing else, across ms / id / en /
zh / ta. 88 clips. A hallucination surfaces as a bare Terima kasih., and so does one of
these. In genuine the phrase sits mid-sentence, which is easier.
Licences vary per speaker (CC0 ×43, CC BY-SA 4.0 ×42, CC BY 4.0 ×3), so every row carries its
own license, author and source_url. Filter license != "CC BY-SA 4.0" to avoid
copyleft.
ban_candidates
Every lexicon phrase crossed against all 7,402 genuine transcripts here (17.8 h):
| verdict | phrases | meaning |
|---|---|---|
safe_candidate |
871 | never in genuine speech, multi-word, frequently hallucinated |
unsafe |
389 | occurs in genuine speech — banning it destroys real transcripts |
weak_evidence |
39,631 | never observed, but too rare or short to be confident |
| phrase | verdict | hallucinated | genuine exact / substring |
|---|---|---|---|
thanks for watching |
safe_candidate | 25,053 | 0 / 0 |
thank you |
unsafe | 31,353 | 0 / 13 |
terima kasih |
unsafe | 1 | 3 / 19 |
Use it in exact mode — drop an output only when the whole transcript equals the phrase.
Caveat: every ms / zh / ta phrase lands in weak_evidence, because the hallucination
counts come from public lexicons that barely cover those languages (6 Malay phrases total).
The classifier works — English demonstrates it — but the Malaysian side needs counts measured
locally.
lexicon
Four public sources merged, normalised (NFC, casefold, punctuation-stripped), deduplicated on
(phrase, lang):
| source key | rows | origin | licence |
|---|---|---|---|
agh_boh |
294 | AGH DSP "Bag of Hallucinations", ICASSP 2025 | MIT |
agh_full |
30,407 | same paper, full non-speech tally | MIT |
hf_noise |
7,889 | sachaarbonel/whisper-hallucinations |
MIT |
granary |
3,028 | NVIDIA NeMo SDP, Granary pipeline | Apache-2.0 |
Top English entries: thank you (31,353), thanks for watching (25,053),
thank you for watching (6,264).
Coverage is uneven. English has 30,443 phrases. Malay has 6. That gap is why this dataset exists.
Published rates for the same model on the same corpus differ by more than 10×. Calm-Whisper
reports 99.97% on UrbanSound8K for large-v3; arXiv:2609.04561 reports 76.08%. The
difference is methodological: the latter counts only output surviving Whisper's own no-speech
filter (no_speech_threshold = 0.6). Always state which you mean.
Corpus composition matters too. arXiv:2609.04561 filtered FSD50K to clips labelled neither
speech, vocal nor music (HR 21.35%). Our nonspeech keeps music — filter kind == "noise" to
approximate their setup.
Synth-Manglish is TTS, not human speech, and is over half of genuine. Filter on source.genuine clips are long (median 9.6 s) while hallucinations happen on short audio.
genuine_isolated is the short counterpart.music may contain singing. nonspeech is the label-verified alternative.speech_in_noise is synthetic mixing. SNR is exact, but channel effects and Lombard speech
are absent.lexicon_synth is synthetic audio. It is training material, not evidence about what models
hallucinate.ABLATION.md.lexicon_raw/ vendored upstream lexicons, unmodified (MIT / Apache-2.0)
external/ HALAS (CC BY 4.0) — 3,611 Earnings-22 clips, human-annotated
hallucination / looping spans across 9 ASR models
licenses/ upstream licence texts + NOTICE.md
HALAS flagged counts out of 3,611. large-v3-turbo hallucinates more than large-v3:
| model | flagged |
|---|---|
| whisper-large-v2 | 1,581 |
| parakeet-tdt-v2 | 1,217 |
| canary-1b | 1,213 |
| canary-1b-flash | 1,099 |
| phi-4 | 1,096 |
| whisper-large-v3-turbo | 1,060 |
| granite | 1,002 |
| whisper-large-v3 | 858 |
| CrisperWhisper | 772 |
All components permit redistribution with attribution.
| component | licence | attribution |
|---|---|---|
reduplication, silence |
CC BY 4.0 | this dataset (synthesised, no recorded human speech) |
music |
CC BY 4.0 | Free Music Archive; per-row artist / source_url |
nonspeech |
CC BY 4.0 | FSD50K (Fhrozen/FSD50k) |
speech_in_noise |
CC BY 4.0 | derived: genuine × FSD50K backgrounds |
librispeech_test_clean |
CC BY 4.0 | LibriSpeech (openslr/librispeech_asr) |
genuine |
CC BY 4.0 | per-row author / source_url |
genuine_isolated |
CC0 / CC BY 4.0 / CC BY-SA 4.0, per row | per-row author / source_url |
lexicon_synth |
CC BY 4.0 | synthesised by Multilingual-Expressive-TTS-1.7B and OmniVoice |
lexicon, targets, malaysian_sources |
CC BY 4.0 | this dataset |
lexicon_raw/agh_* |
MIT | AGH Signal Processing Group |
lexicon_raw/hf_whisper_hallucinations_phrases.csv |
MIT | Sacha Arbonel |
lexicon_raw/granary/* |
Apache-2.0 | NVIDIA, NeMo-speech-data-processor |
external/halas_* |
CC BY 4.0 | HALAS authors (AGH DSP) |
The synthetic audio contains no recorded human speech, so it carries no speaker-consent or
PII obligations. genuine and genuine_isolated are redistributed under their own licences;
see licenses/NOTICE.md.
Note on generators: OmniVoice's code is Apache-2.0 but its released weights are CC-BY-NC.
Multilingual-Expressive-TTS-1.7B is ours.
The lexicon records what an ASR model wrongly generates on audio containing no speech. Of 40,891 phrases, roughly 586 contain profanity and 583 violence-related terms; 8 are sexual. These are model errors, not anything a person said. They are kept because removing them would misrepresent the failure mode.
Dataset: Scicom-intl/Whisper-Hallucination. Code:
https://github.com/Scicom-AI-Enterprise-Organization/Whisper-Hallucination
Built on:
arXiv:2501.11378)arXiv:2505.12969)NeMo-speech-data-processor, Granary pipeline.